Skip to content
Pouncity — 2nd Runner-Up, Rethink AI-First Buildathon

Yash Chopra · AI product builder

I turn business workflows into working AI products.

Explore the applications I've built, the decisions behind them, and what I'm testing next. My background spans operations, quality, and enterprise delivery.

Selected work

Pouncity, an award-winning team build, and Kirana, a voice-to-cart agent system I built solo — then two public AI applications, a private enterprise platform, and an early retrieval project. Each one states what it does, the decision behind it, and its current limit.

Award-winning · 2nd Runner-UpLive · Team build

Pouncity

Pet parents own their pet’s record — and hand it to a sitter or vet in one tap, without losing control of it.

  1. 01
    The obvious build

    Most pet apps in India sell an AI diet plan. We counted 6+ already doing it — that’s table stakes, not a product.

  2. 02
    What the reviews said

    Owners of the closest all-in-one apps were locked out of their own pet’s data behind a paywall. And the handover to a sitter or vet? Still a scribbled Google Doc, if it existed at all.

  3. 03
    What we built instead

    One living diary the pet parent owns — feeding logs, grooming and vet reminders — handed to a sitter or vet by link in one tap, without giving up control of it. The AI diet and grooming plan is the starting point, not the pitch.

Open Pouncity pouncity.vercel.app
Team
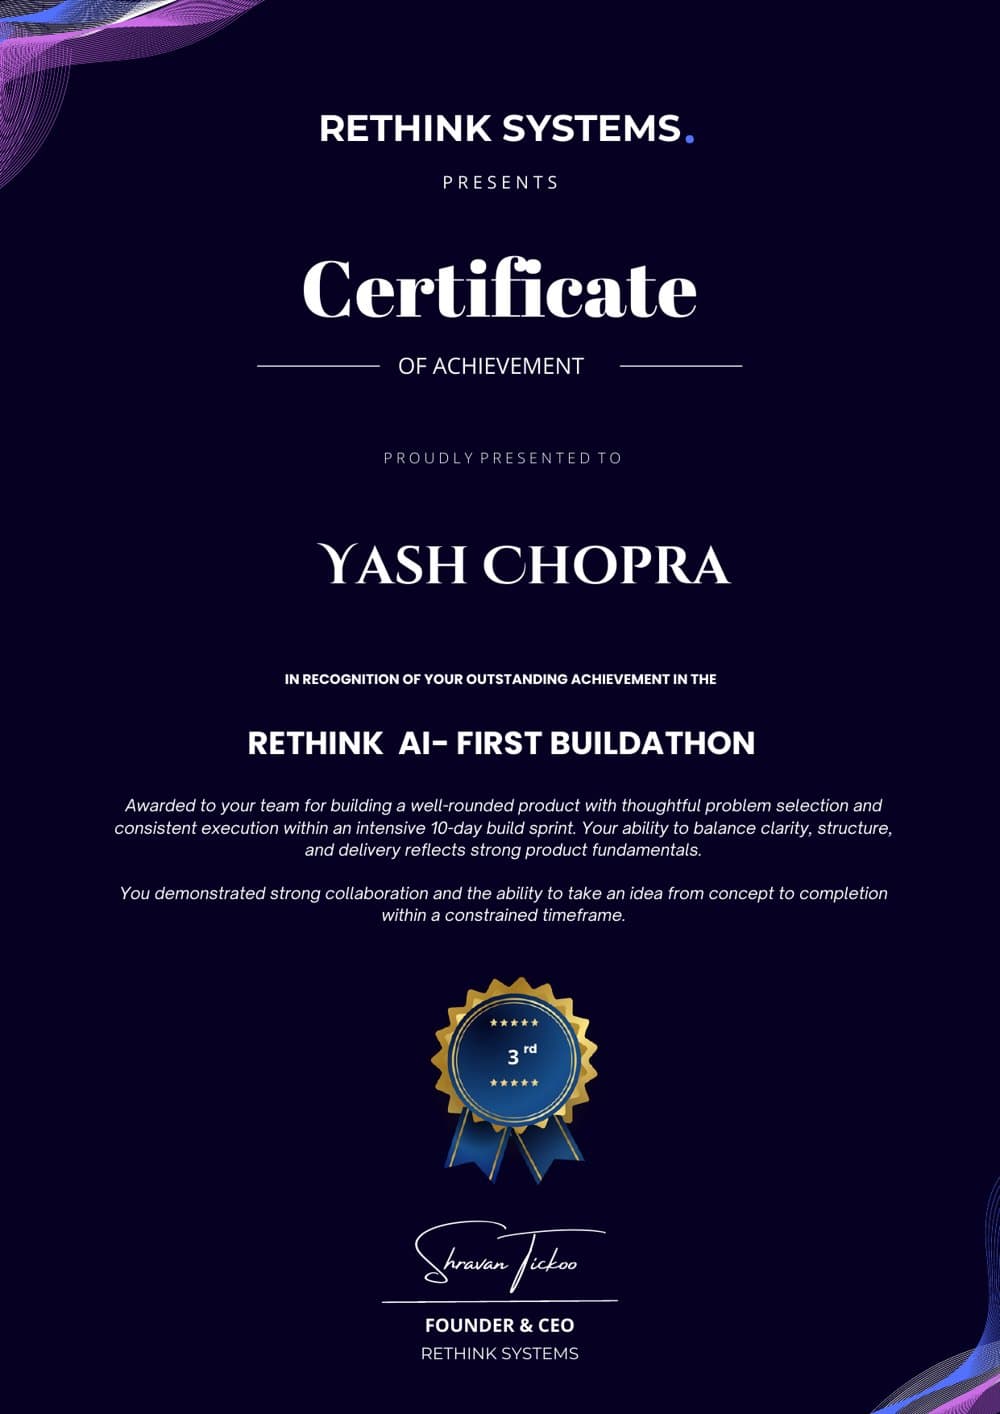
Built with Team Avengers in a 10-day build sprint at the Rethink Systems AI-First Buildathon (AIPM programme). 2nd Runner-Up (3rd place).
Next
We’re not stopping at the demo — Pouncity is being taken further.
Current limit
A 10-day buildathon build; real-world usage hasn’t been measured yet.
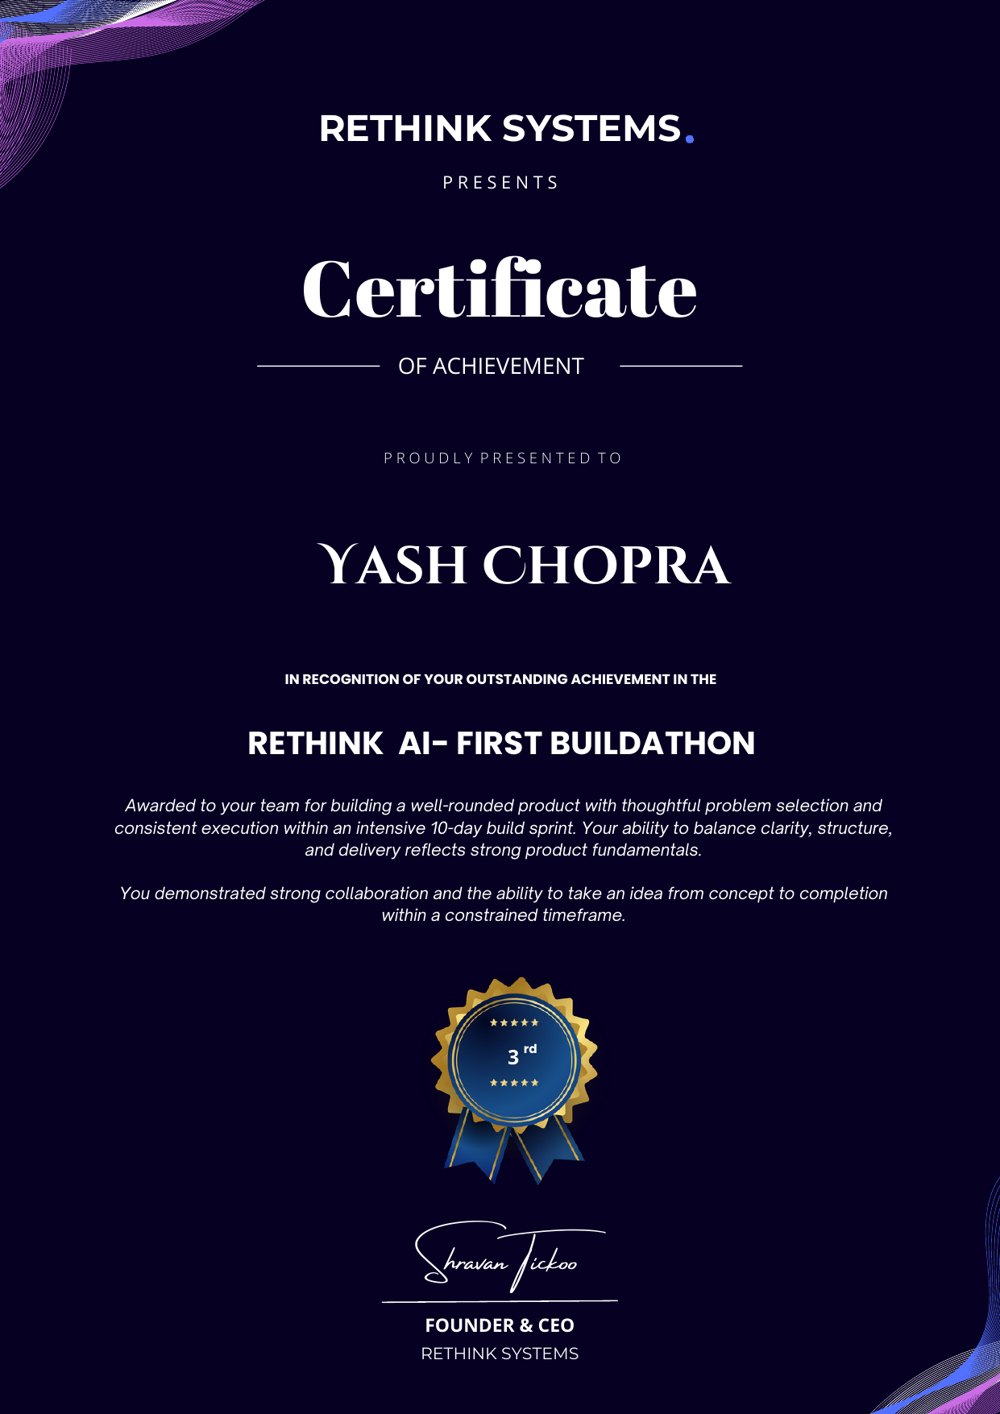
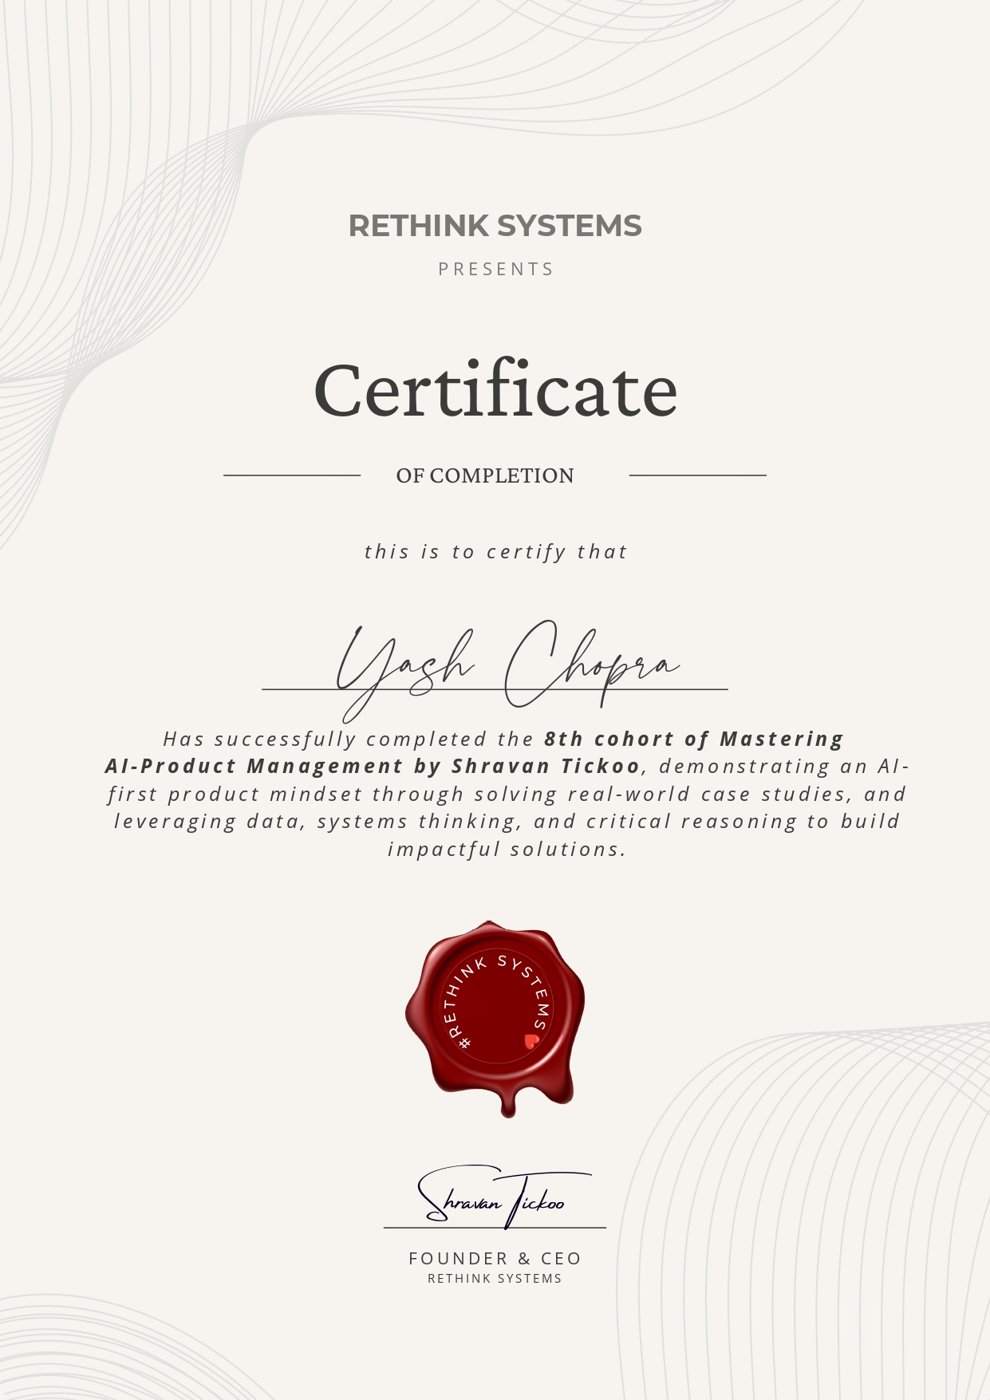
Rethink Systems certificate of achievement awarded to Yash Chopra — Rethink AI-First Buildathon, 3rd place
Certificate of achievement · view full size →
Featured · Solo buildPersonal · Private repo

Kirana

A voice-to-cart agent system for groceries: say it — or photograph your list — through the day, compare every vendor at night, and keep the final purchase in human hands.

5
vendors live-verified
117
commits since 16 Sep
0
automated payments
Two safety models
Zepto and Swiggy Instamart through their official MCP, compare-only. Blinkit, BigBasket and DMart through browser automation that builds the cart and stops at payment.
Key decision
Agents can compare and fill a cart, but never pay. A wrong automated purchase costs more than one extra tap. Read more →
Current limit
Personal use on my own accounts. The browser vendors (Blinkit, BigBasket, DMart) run against a signed-in Chrome on my machine, and supermarket delivery-fee estimates still need tuning.

SpotCheck

Public demo · Pre-validation

Review AI-assisted finance work before sharing it.

Role
Solo build: product, implementation, testing, and deployment.
Key decision
When the coach invented assumptions, I made every inference a “[confirm: …]” placeholder the user approves. Read more →
Current limit
Its ratings have not yet been validated against human reviewers.
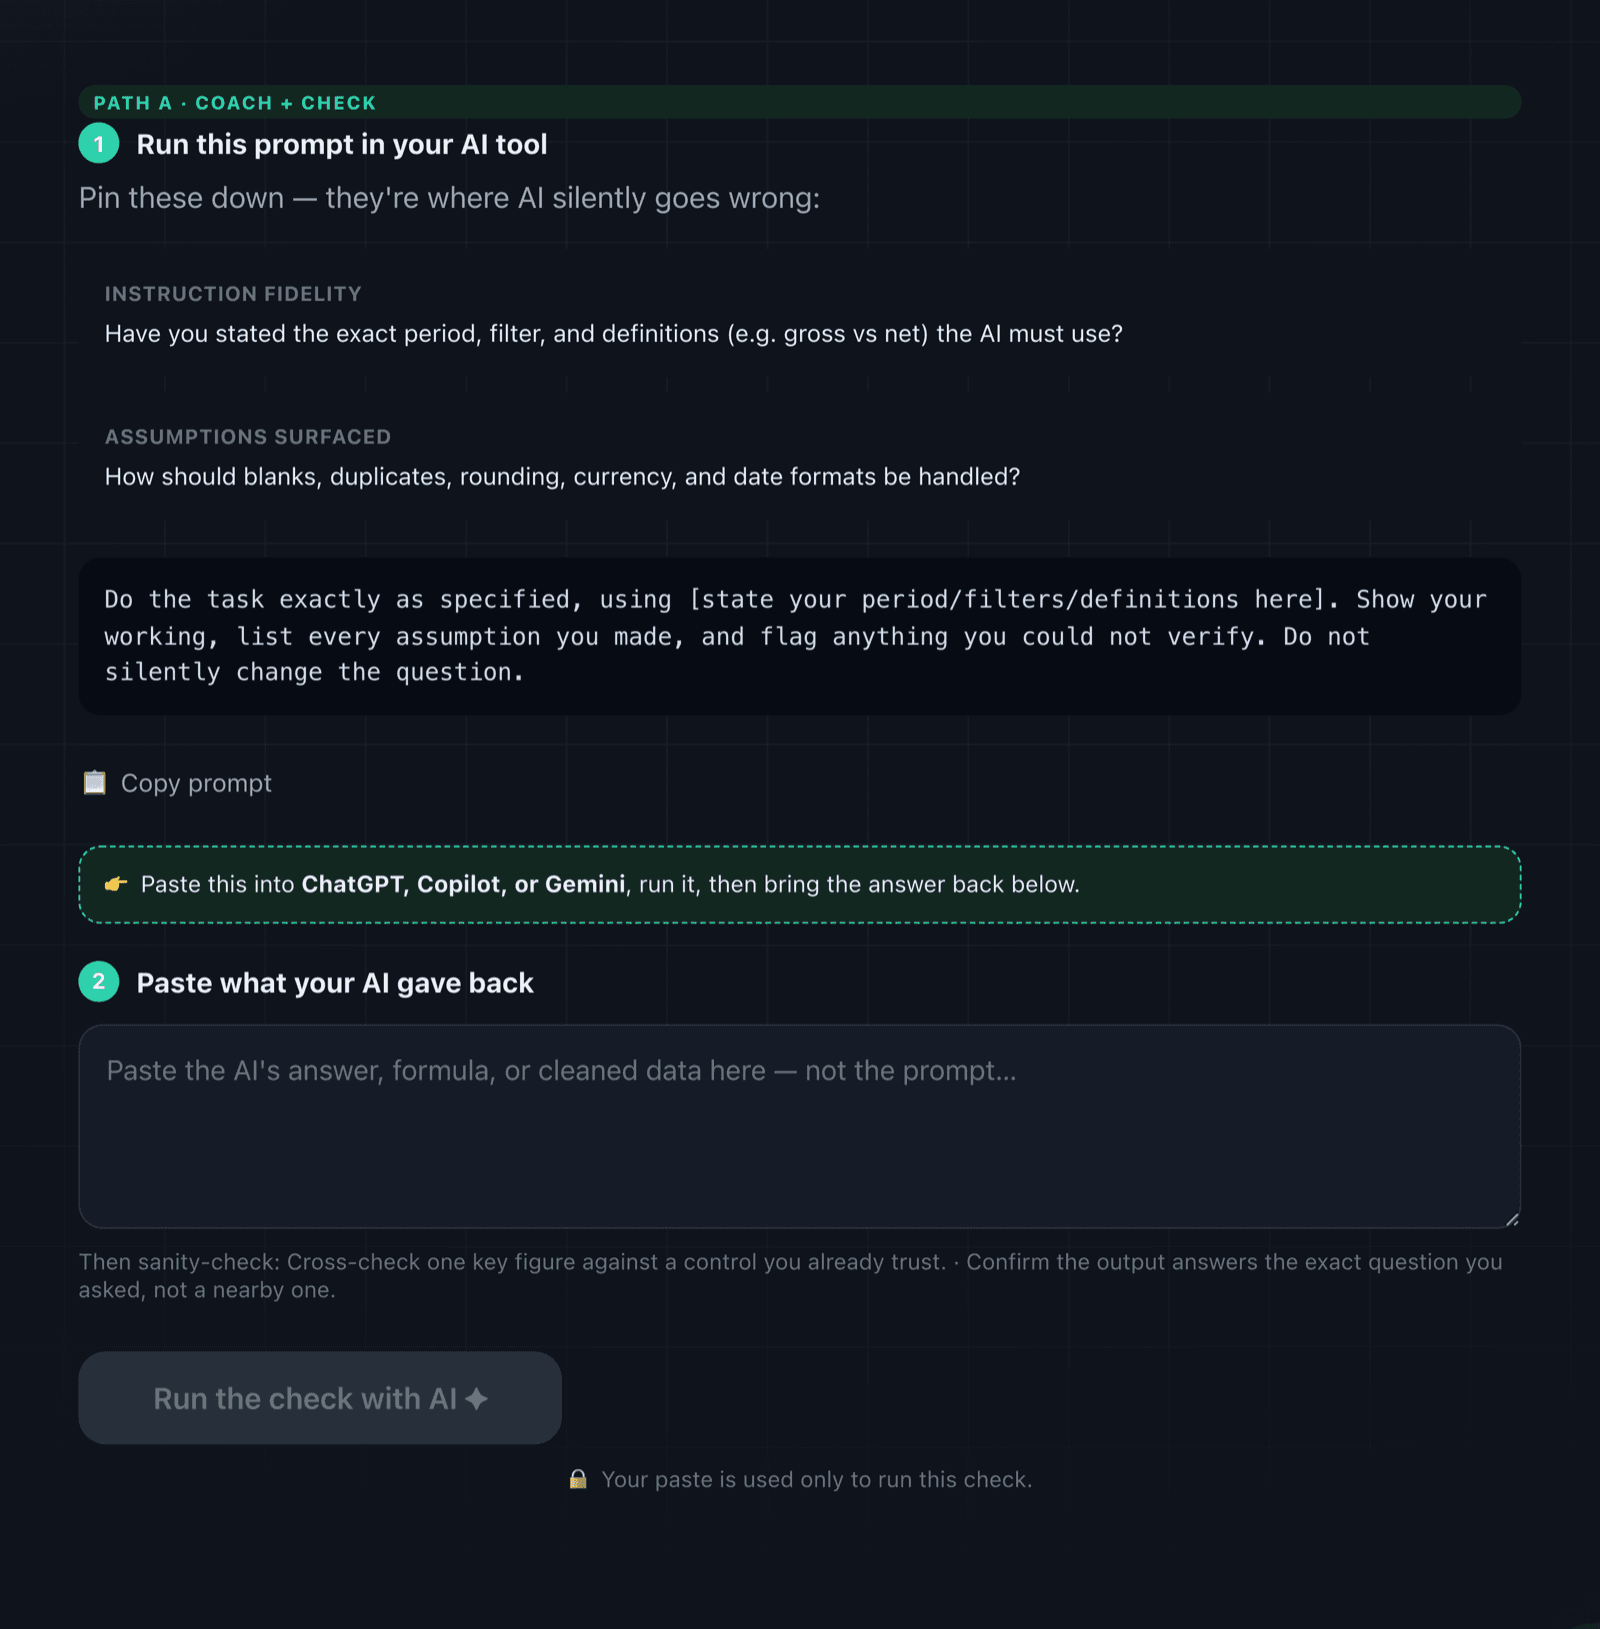
SpotCheck's coach-and-check workflow: a hardened prompt with a bracketed placeholder to confirm before running, then a box to paste the AI's answer for a seven-dimension check.
Live demo · coach + check
How it works

Frontier Digest

Public demo · Validation in progress

Explore AI research with answers linked to source articles.

The web demo sleeps when idle; its first response may take tens of seconds.

Role
Solo build: retrieval, web application, and Telegram integration.
Key decision
Source lookup stays separate from semantic search — mixing them once returned wrong-lab sources. Read more →
Current limit
Citation quality has not been formally measured.
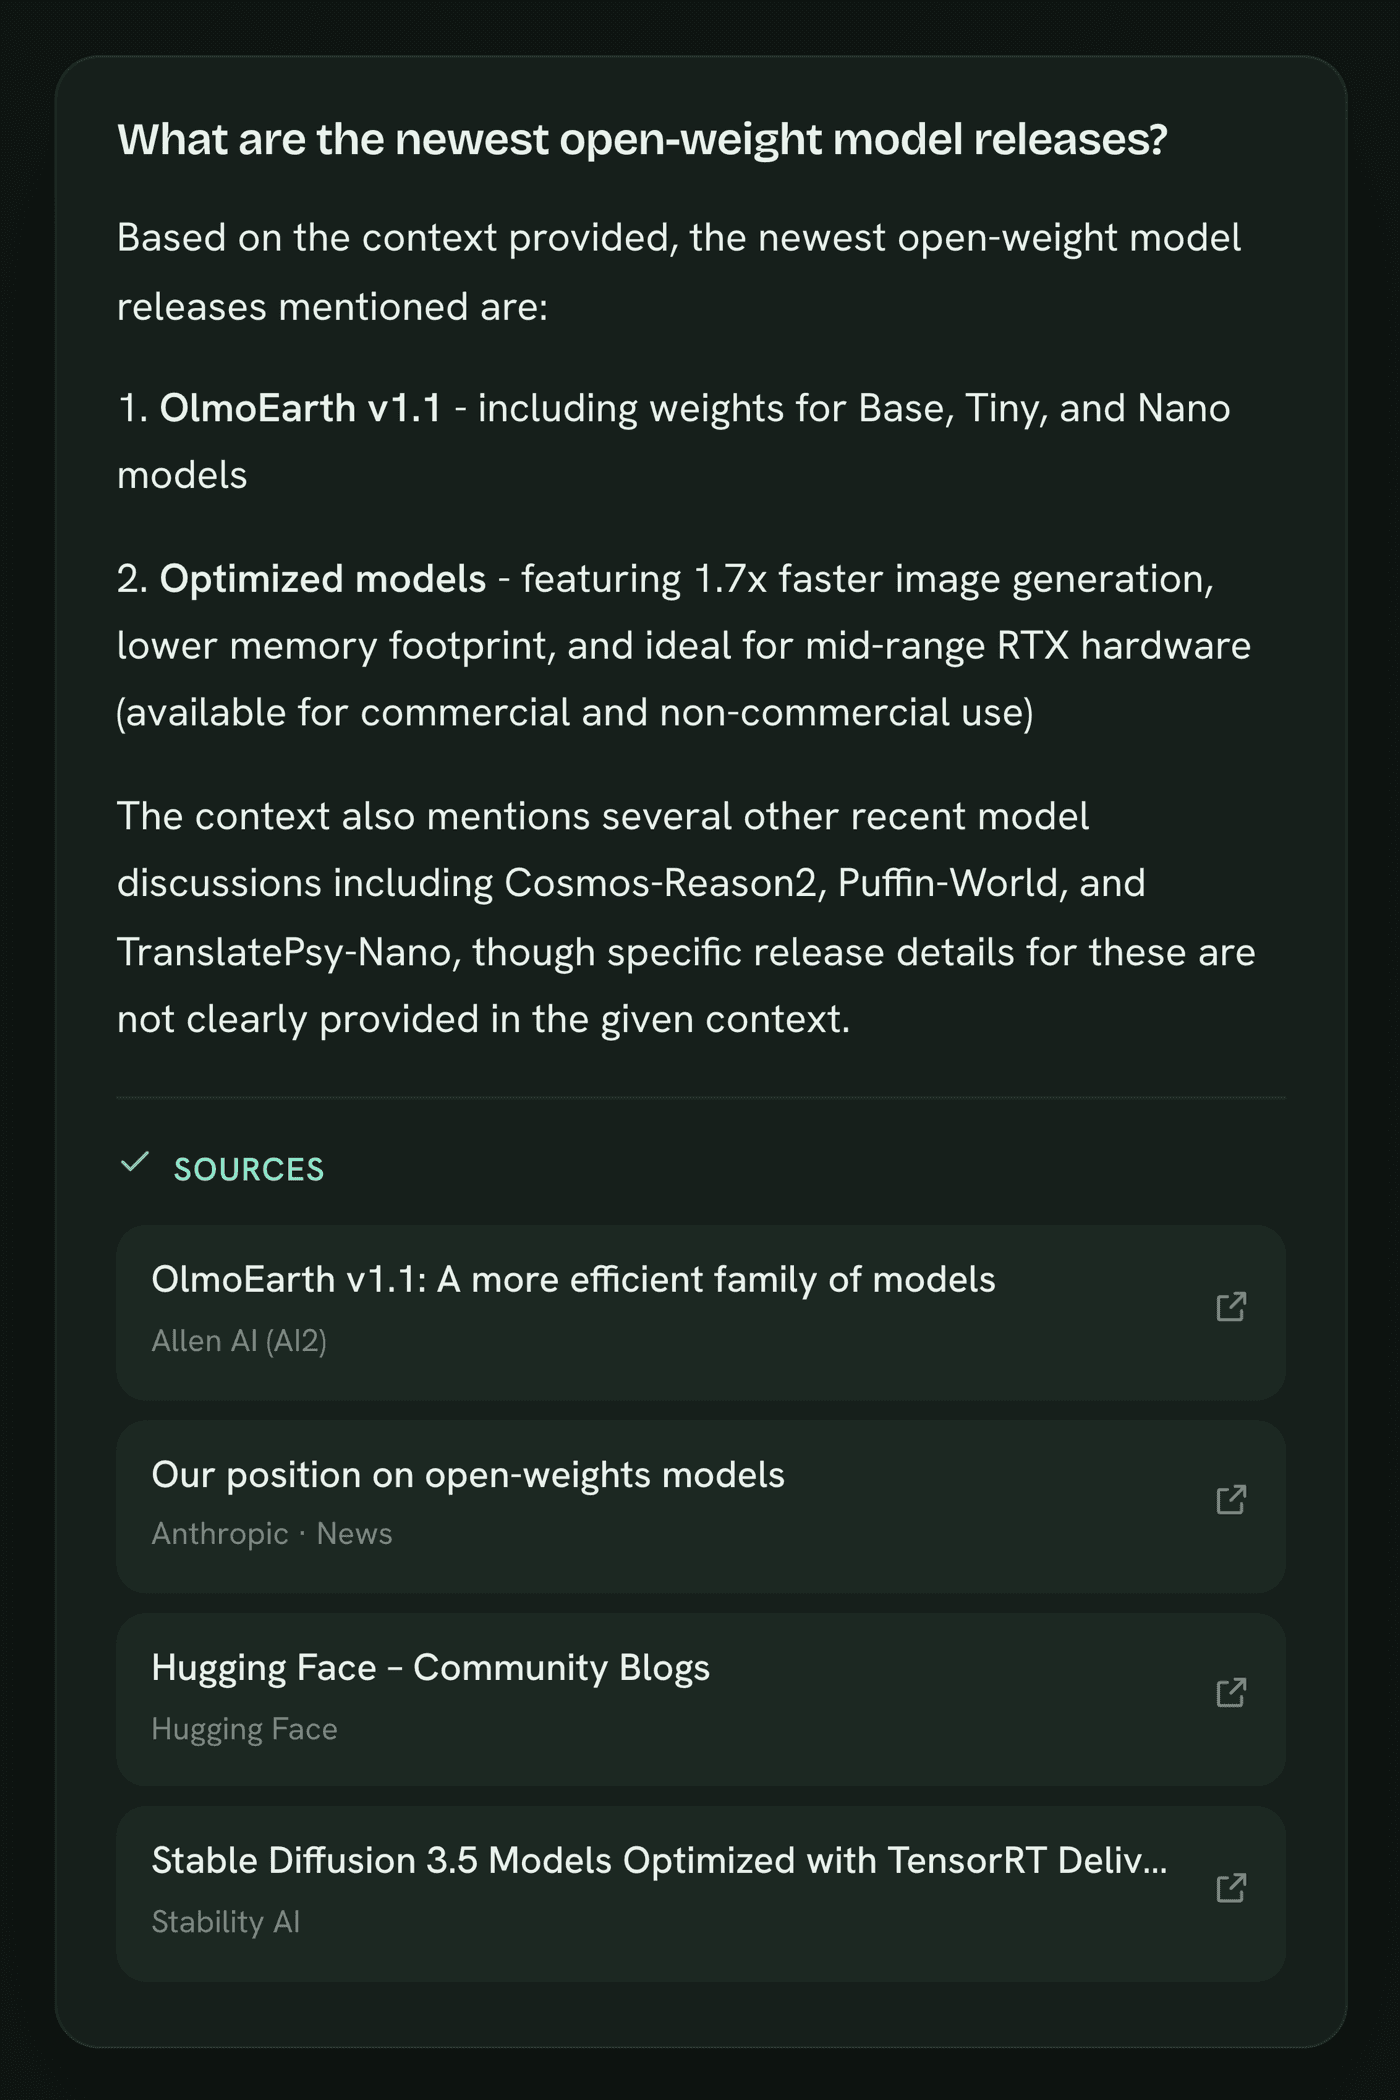
Frontier Digest answering a question about open-weight model releases with a grounded summary and four linked sources.
Live demo · answer + sources
How it works

Questboard

Enterprise · Private deployment

An engagement platform for employee challenges, submission reviews, rewards, and leaderboards, with separate admin, leadership, and employee roles.

Private enterprise deployment. Public demo and code are not available.

Built with React · Vite · Tailwind · Supabase

Request a Questboard walkthrough
Early project

DocQA

A terminal tool for asking questions over a local document collection. Its retrieval core is tested independently of the language model.

View code

How I look at a problem

Every project here started the same way: find where the obvious answer stops being useful, then build the smallest thing that proves the better one. Five rules I keep coming back to.

  1. 1

    Start where the table stakes end.

    If six apps already do it, building a seventh isn’t a product. I look for the part everyone skips — for Pouncity, that was who owns the pet’s record and how it gets handed over.

    Seen in: Pouncity →
  2. 2

    Read the complaints, not the feature lists.

    Competitor reviews and real workarounds say more than landing pages. Paywalled data and Google-Doc handovers told us what to build. It’s a habit from 13+ years in operations: the real workflow usually lives in the workaround.

    Seen in: Pouncity →
  3. 3

    Make the AI show its assumptions.

    A model that quietly guesses is worse than no model. SpotCheck turns every inference into a “[confirm: …]” the user approves; Frontier Digest says what its sources don’t cover; Kirana sends offers it can’t trust to a review queue.

    Seen in: SpotCheck →
  4. 4

    Design the data path before the prompt.

    SpotCheck’s model only ever sees a bounded summary of the spreadsheet. Frontier Digest keeps semantic search and lab lookup apart — mixing them once returned wrong-lab sources. Semantic search is not a filter.

    Seen in: Frontier Digest →
  5. 5

    Ship in days. Claim only what’s measured.

    A working thing in front of people beats a deck about one. Every project here lists its current limit next to what it does — a demo is not a validated system.

    Seen in: Shipping log →
~/yash — ship-log
$ git log --since=2026-08 --summary
  • Aug 21–24spotcheck59 commits
    ↳ 4 days, idea → public demo; moved the AI to Claude Haiku 4.5
  • Sep 01–13rag-agent10 commits
    ↳ DocQA — retrieval core tested apart from the LLM
  • Sep 04–11blog-rag110 commits
    ↳ Frontier Digest — web + Telegram, Sentry, CI
  • since Sep 11blog-ragdaily
    ↳ scheduled job refreshes the digest every day
  • Sep 16 – Oct 2kirana117 commits
    ↳ voice + photo capture → compare → cart agents; 5 vendors live-verified
  • Buildathonpouncity10 days
    ↳ team sprint → 2nd Runner-Up, AI-First Buildathon
$

Counts from git history as of 2 Oct 2026 (kirana is a private repo). Frontier Digest excludes automated daily-refresh commits.

What I can build

Bring a workflow, a document collection, or an early product idea. These are the kinds of AI applications I can scope and build — each shown in the work above.

AI-assisted review workflows

A tool that checks AI-assisted work against your criteria and flags what needs a person’s attention.

Search & answers over documents

A searchable collection that answers questions with links back to the source passages.

Agents that act — with a checkpoint

Voice or chat in, agents that search, compare and prepare the action, and a human who approves before anything irreversible.

Internal tools for operations

A web app for tasks, submissions, approvals, and reporting, with roles shaped around the people using it.

Not sure where AI belongs? Describe the task →

Decisions from the work

A few real choices from the projects — the problem, what I decided, why, and what I can and can't yet claim from it.

SpotCheck
Problem
While testing a revenue example, the pre-flight coach invented filters — “exclude intercompany, exclude refunds” — as if it knew the user’s ledger.
Decision
Anything the coach infers now becomes a “[confirm: …]” placeholder the user must approve, never an asserted fact.
Reason
A coaching product can’t commit the silent-assumption mistake it exists to catch.
Result
The coach no longer asserts unstated filters. Whether analysts find the review useful is still untested.
Read the full story
Kirana
Problem
Letting the agent check out would save a tap — and let a wrong product match or a mis-read offer spend real money.
Decision
Agents compare and fill carts but never pay. MCP vendors are compare-only; browser vendors stop at payment, and you pay and enter the OTP.
Reason
The cost of one wrong automated purchase is higher than the cost of one extra human step.
Result
No automated payment, by design. Offers the system can’t trust go to a review queue instead of the total.
Read the full story
Frontier Digest
Problem
Combining free-text search with lab filtering once returned sources from the wrong lab.
Decision
The typed box does semantic search; the lab chips and stats do plain lookup — the two paths stay separate.
Reason
Conflating “find similar text” with “show me this lab” is what produced wrong-lab sources.
Result
The two retrieval paths are separated by design. Citation-support quality is still not formally measured.
Read the full story

About

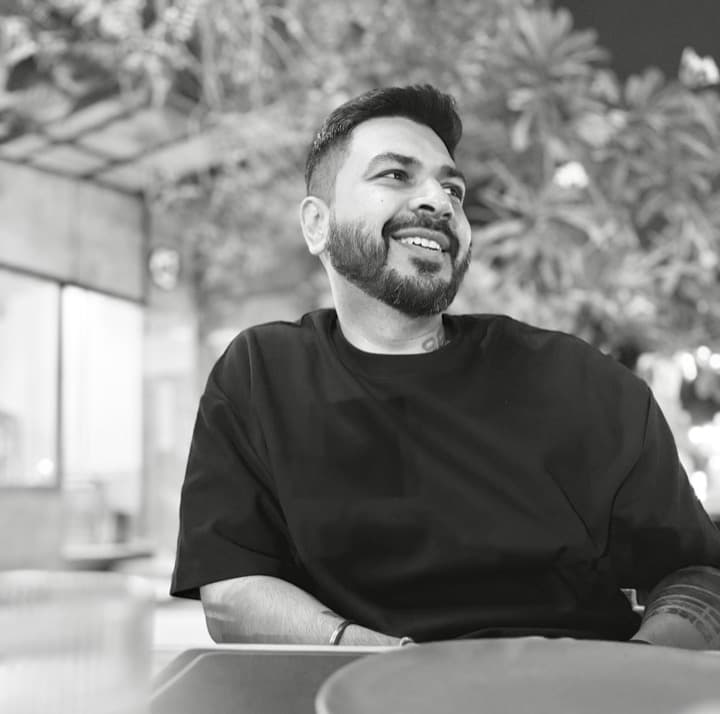
Portrait of Yash Chopra

I build AI applications from the initial problem through implementation and deployment. I use AI-assisted development and review what the tools produce.

My earlier work spans operations, quality, and enterprise delivery. That experience shapes how I define workflows, handle constraints, and distinguish a working demo from a system that has been validated in use.

Enterprise delivery — career totals
13+ yearsoperations, quality & delivery
47+enterprise programs
5SaaS products
₹13+ Crcost savings

Self-reported totals from 13+ years in enterprise operations and delivery roles (through Delivery Head, Welspun) — separate from, and not a measure of, the public AI applications above.

Career so far
  1. 2013
    Operations career begins
  2. 2021
    Delivery Head — Welspun
  3. Late 2024
    Started building AI applications
  4. 2026
    Shipped SpotCheck, DocQA & Frontier Digest
  5. 2026
    Building Kirana solo — voice, compare and cart agents
  6. 2026
    AI Product Management, Rethink Systems · Pouncity — 2nd Runner-Up, AI-First Buildathon
Certifications & recognition

Delivery & quality — PMP · Lean Six Sigma Black Belt · CSPO · Agile Certified · ISO 9001 / 14001 / 45001 Internal Auditor · SDA Bocconi Future Leader

Let's talk

Have a workflow worth automating, an AI product idea to prototype, or an opportunity to build something together? Tell me what you're working on and where you need help.

Opens your email app.